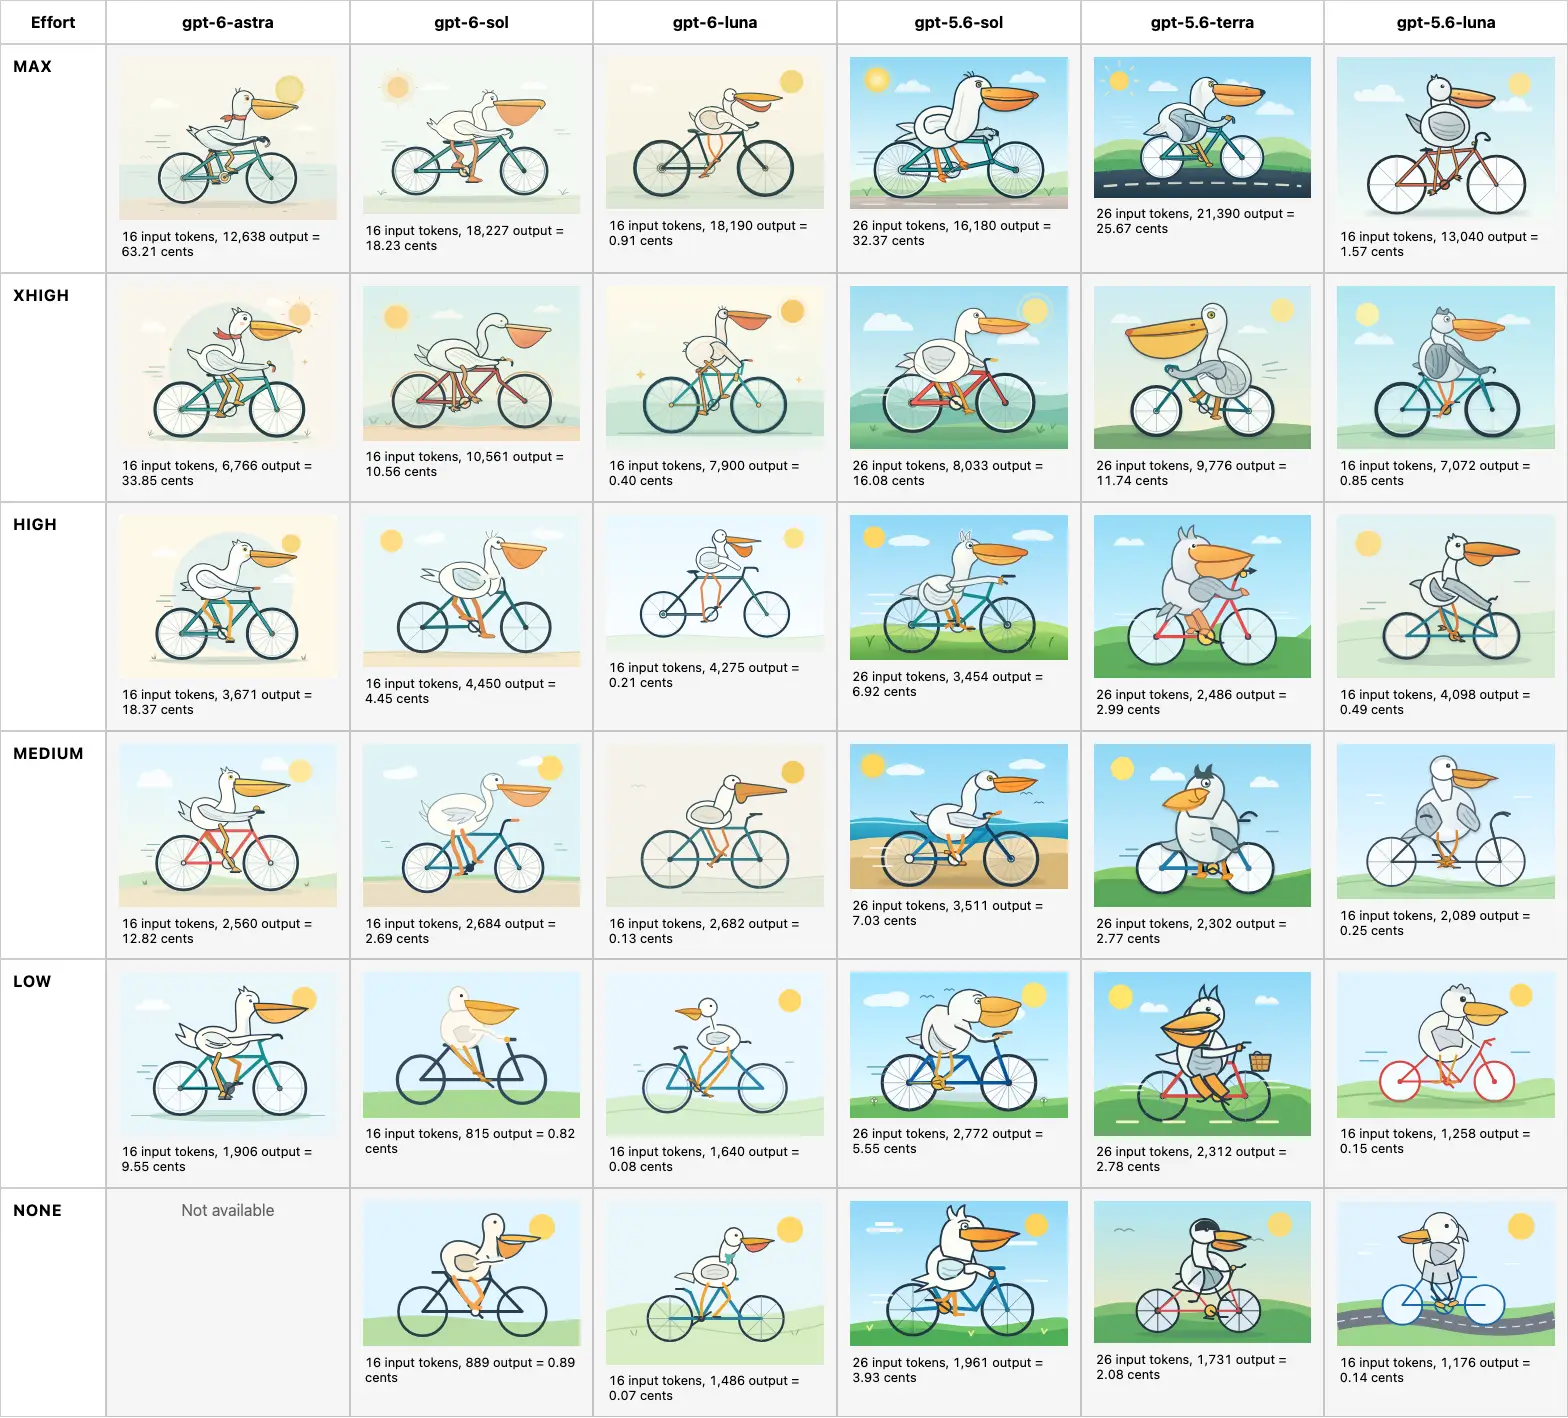
Claude Opus 5.5, GPT-6 Sol and Luna with half-price economics
The pricing compression across three new models changes what's economically viable for longer-context agentic workflows in your own apps.
Opus 5.5 vs. GPT-6 blind models compared on real work
A blind test across your actual workload types (prototyping, PRDs, agents) tells you more than any benchmark about which model to default to.
AI evals what teams skip and how to automate it
It names the planning step teams skip before writing eval metrics, which is exactly the gap that makes model comparisons unreliable.
Motion Studiomerges visual editing with a fast AI agent for animation tuning
An AI agent embedded directly in a visual animation editor could remove the code-rewrite step you currently tolerate when tuning easing and timing.

Variance in AI products breaks trust when unexplained
It gives you a concrete design principle for any AI feature you ship: users benchmark against the fastest response they've seen, so unexplained variance reads as broken, not just slow.
Chrome 154 self-sizing iframes arrive
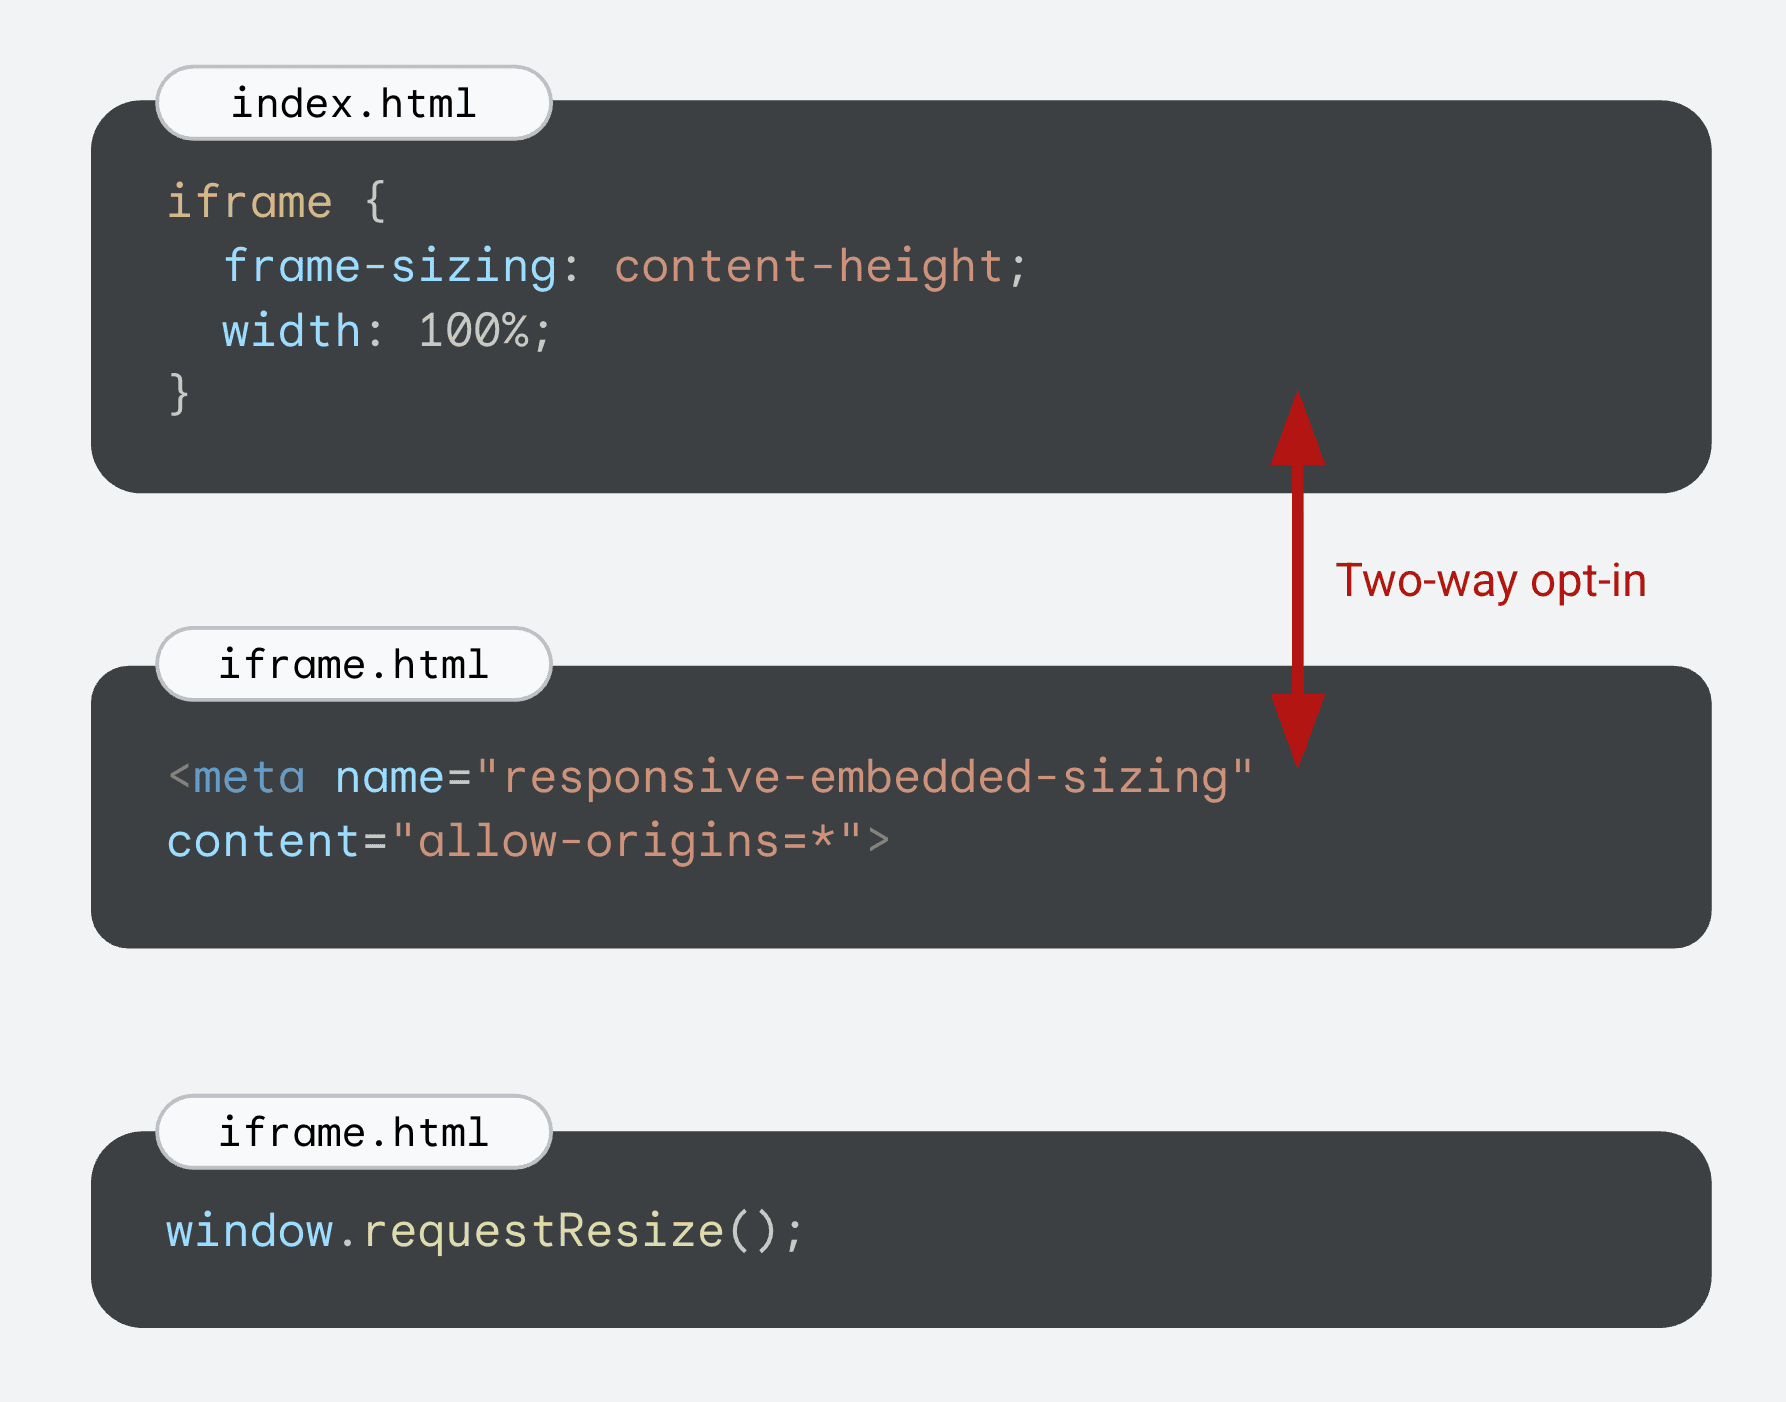
A native CSS property for auto-resizing iframes removes a JavaScript workaround you've likely had to hand-roll for embedded widgets.
Responsive CSS Grids filling the last row without complex selectors
A cleaner gap-based technique for grid last-row filling is a small but real upgrade over nth-child hacks in your Next.js layouts.

Templo for DeafCity Hub translates sign language gestures into a motion-coded brand identity
Templo's use of motion-captured sign language as the literal generative input for a visual identity system is a model for grounding interaction design in specific human gesture rather than generic motion.

Livelymerge connects Cursor to live code execution in minutes
Wiring an LLM agent directly into a live coding environment in under an hour previews how tight the feedback loop between AI and running code is becoming.
Claude Opus 5.5, GPT-6 Sol and Luna with half-price economics
The pricing compression across three new models changes what's economically viable for longer-context agentic workflows in your own apps.
Run Lenny's blind taste test format on your own recent frontend prototyping task across Opus 5.5 and GPT-6 Sol before picking a default.