Coding agents crossed into reliable territory in late 2025
Worth testing personally whether Opus 4.5 or GPT-5.1 actually change your day-to-day build loop, since the claim is that the threshold from novelty to reliability has already passed.


Entry-level craft disappears when AI automates the apprenticeship
Names a real risk for anyone running a studio with junior staff: automating the tedious tasks that used to double as training.
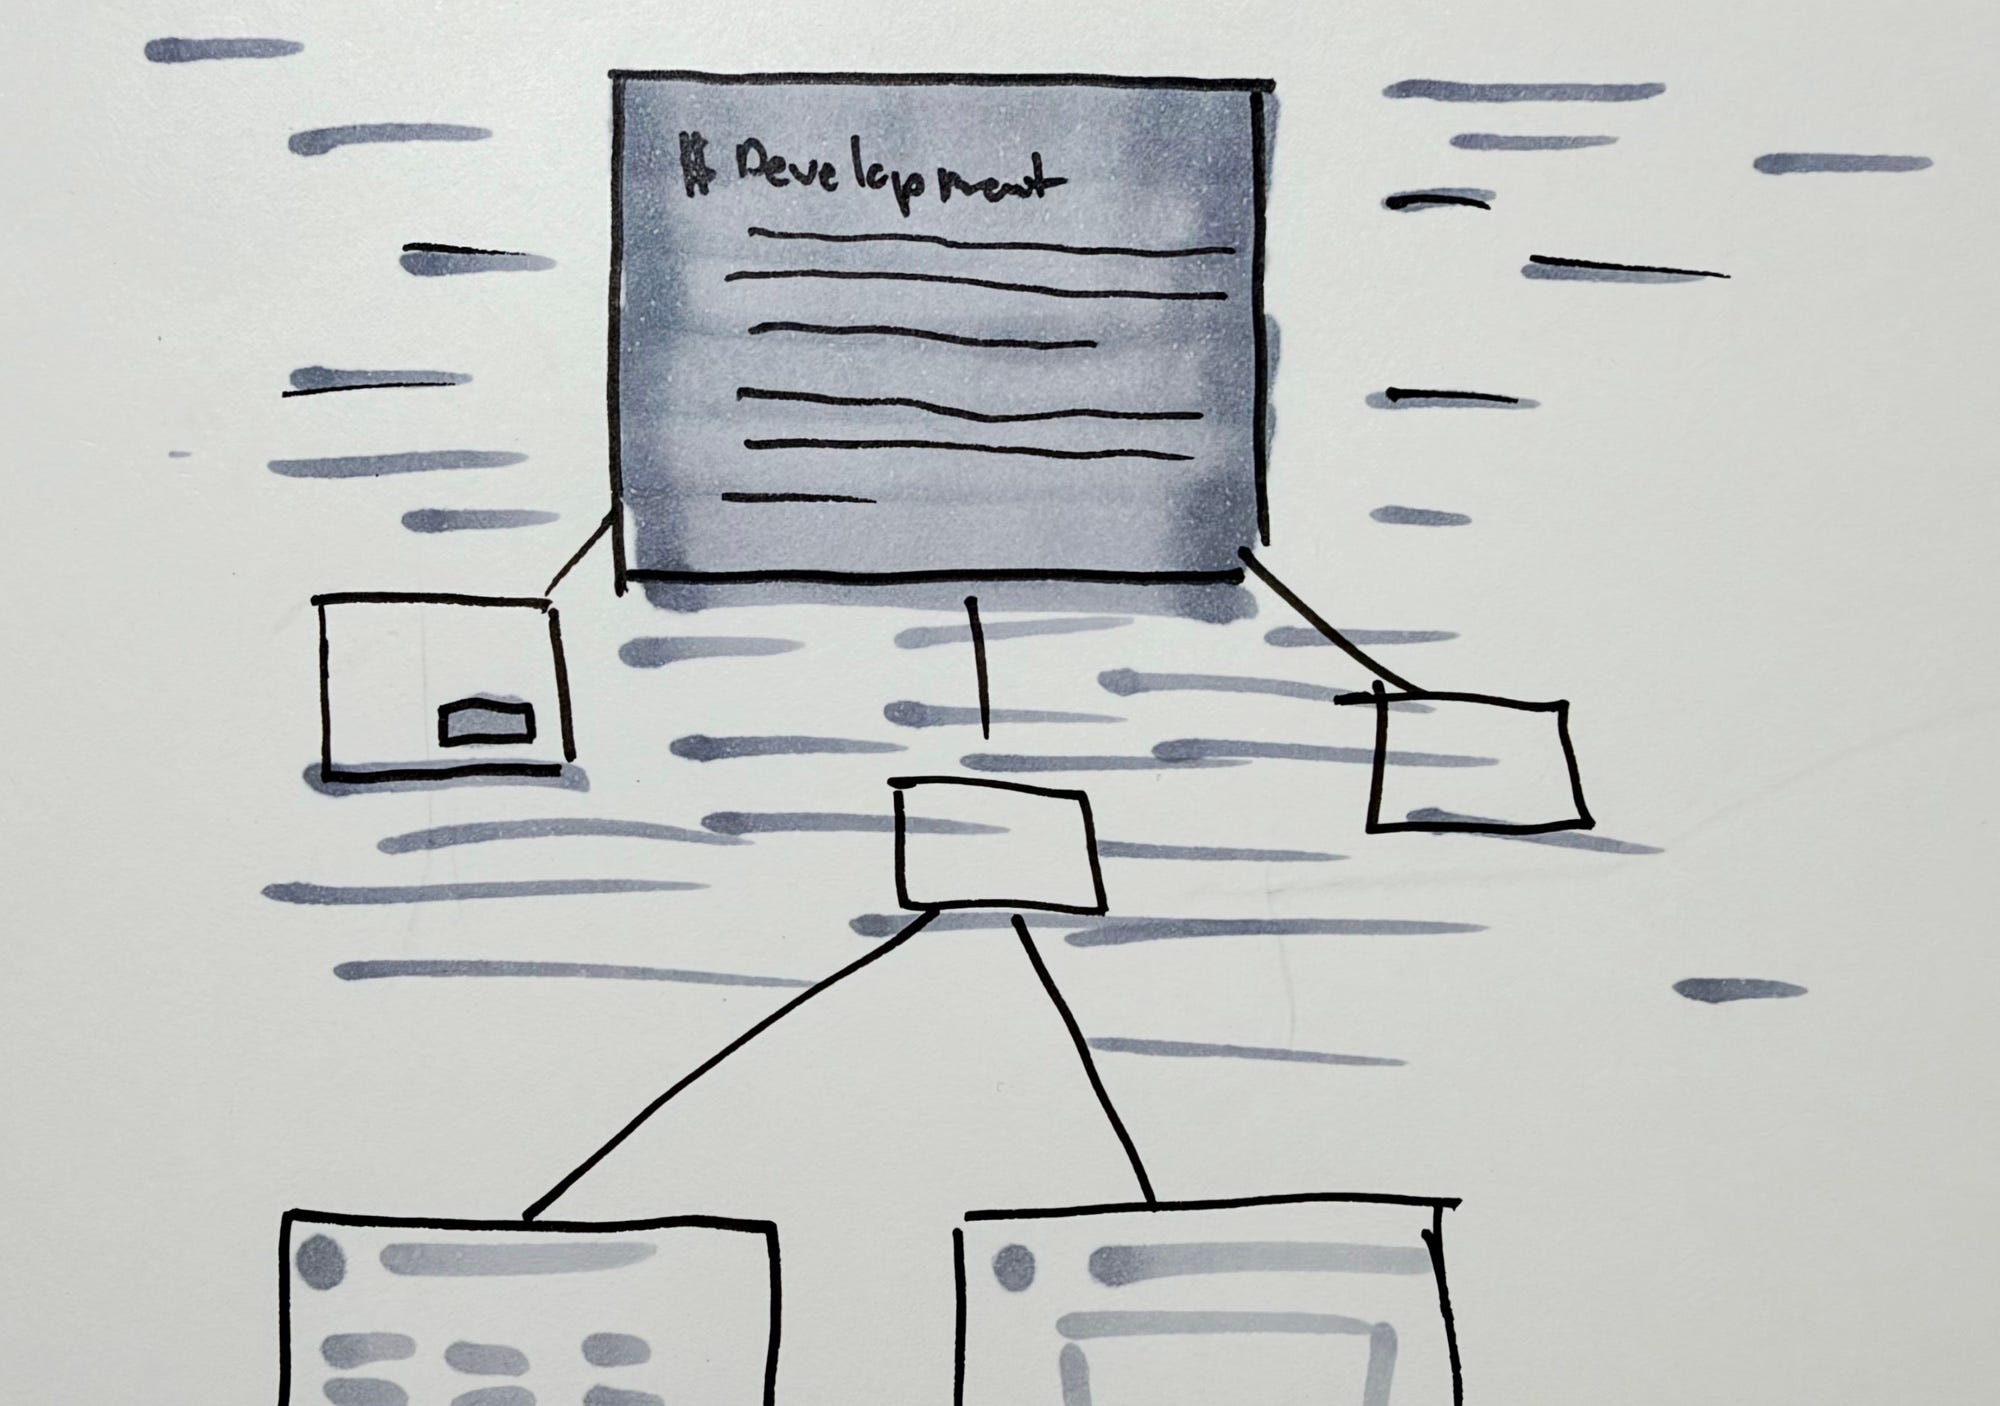
Personal software as a spectrum between headless and app interfaces
Offers a useful frame for your own app-building: design each tool for proximity to the task at hand rather than picking one interaction model to rule them all.
WebP adoptionoutperforms PNG and JPEG for screenshots and web images
A one-line reminder to default to WebP for screenshots and web graphics if you haven't already switched.
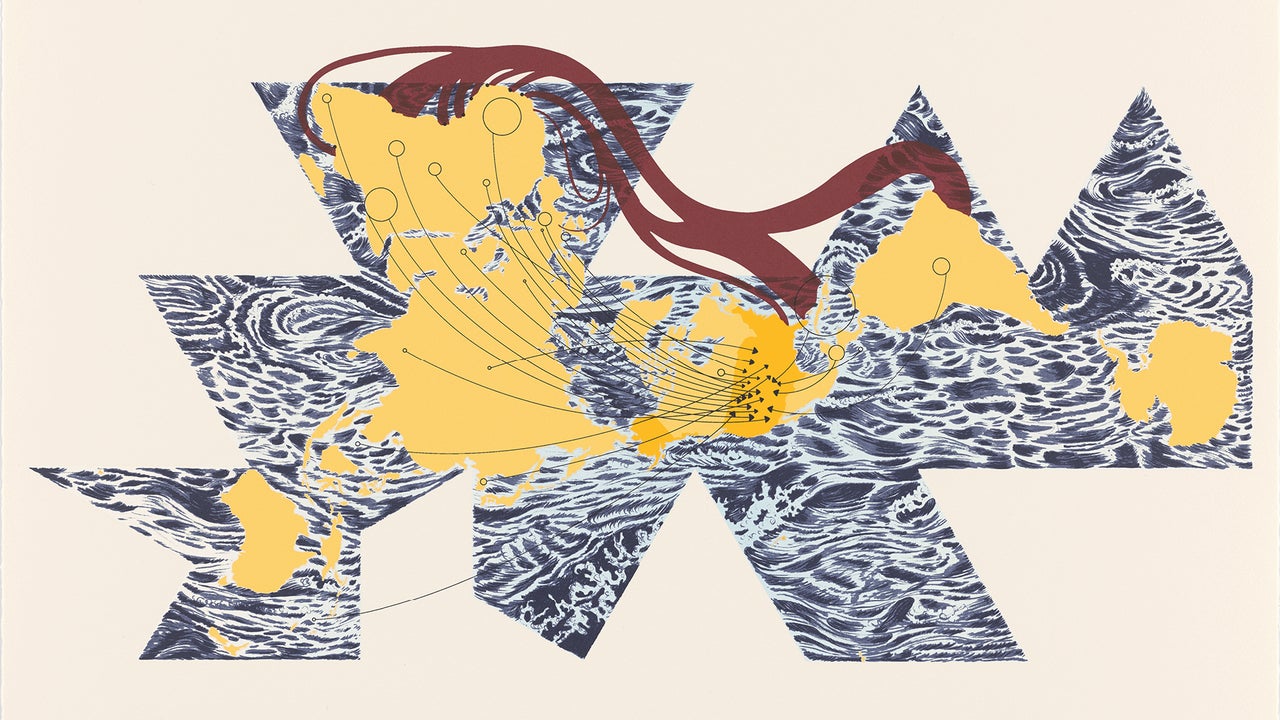
MoMA's Information Design exhibition shows how visual systems convey facts and values together
A concrete case study in making abstract data (climate warming stripes) viscerally legible, useful when your interfaces need to carry weight beyond decoration.
Bluesky bot checker identifies reply bots by behavioral signals
A small, well-scoped example of vibe-coding a pattern-detection tool, worth studying as a template for narrow AI-assisted utilities rather than open-ended agents.
Coding agents crossed into reliable territory in late 2025
Worth testing personally whether Opus 4.5 or GPT-5.1 actually change your day-to-day build loop, since the claim is that the threshold from novelty to reliability has already passed.
Pick one piece of "boring" junior work your team still hands off manually and ask whether removing it would also remove the learning, not just the labor.